
Business Tools: How To Select And Integrate Solutions For Daily Operations

Integrating Tools into Existing Workflows and Systems
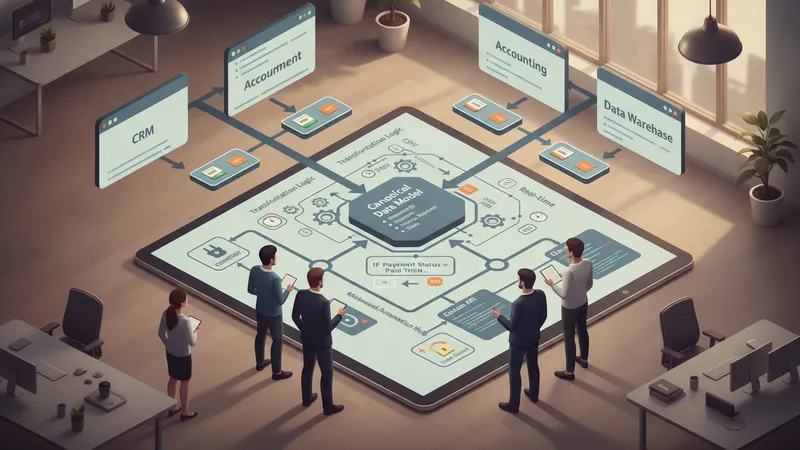
Integration planning typically starts with a data map that identifies source systems, data formats, frequency of updates, and transformation needs. U.S.-based teams often document required fields for financial reporting or customer records to ensure consistent imports and exports. Defining canonical data models can reduce repeated mapping work when multiple systems must share information, such as invoice status flowing from project management to accounting.
Integration methods vary by technical profile: native connectors may provide quick links between common SaaS products, while middleware platforms like Zapier or enterprise integration platforms enable conditional logic and multi-step automations. Where no connectors exist, teams may use vendor APIs to build custom integrations; these efforts often require attention to authentication, error handling, and rate limits. Planning for the effort and maintenance burden is a common consideration in U.S. implementations.
Identity and access management are often part of integration work. Implementing SSO and role-based permissions can centralize user lifecycle management and reduce administrative overhead. In U.S. organizations subject to state privacy regulations, teams typically ensure that integrations do not expose sensitive fields unintentionally and that encrypted channels and audit logs are in place to track data movement between systems.
Testing, staging, and rollback procedures are practical steps to reduce disruption. Many U.S. teams adopt a staging environment to validate transformations and user permissions before production deployment. Rollback plans commonly include data snapshots or reversible migration scripts to restore prior states if integration issues affect accounting balances or customer records. These safeguards are part of operational risk management during tool adoption.